Monitoring All Your Systems
Monitor websites, APIs, domains, servers and containers — with alerting, incident management and status pages — from one platform.
This is what you get
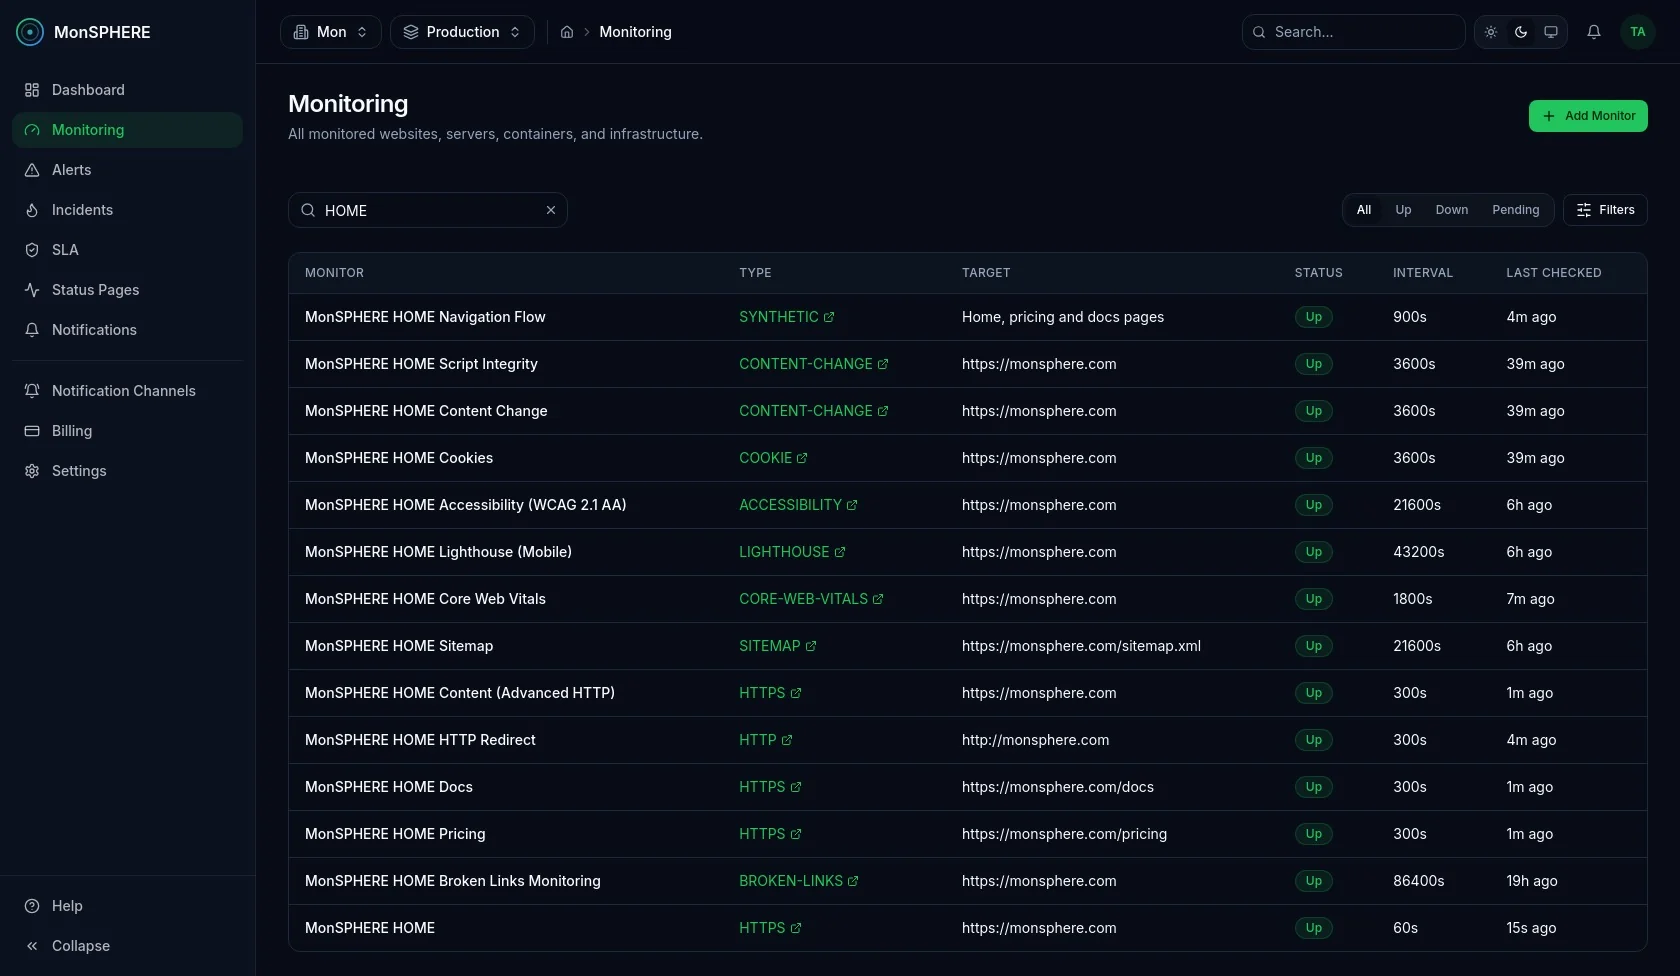
Real screens from the MonSPHERE app — not a mockup.
What can you monitor?
Uptime, security, performance, SEO and infrastructure — every check is a real monitor type with its own alerts and history.
Is it up, and does it answer correctly — from every region you assign.
Website Monitoring
Track uptime, response time, and page performance from every region you assign.
Advanced Website Monitoring
Regex assertions, forbidden keywords, and custom request headers and bodies — check what a page or API actually returns, including authenticated endpoints.
Ping Monitoring
ICMP checks for raw network reachability and latency tracking.
TCP Monitoring
Check that a host's port accepts connections, with connect time tracked from every region you assign.
Advanced TCP Monitoring
TCP over TLS plus send/expect validation — confirm a service actually answers correctly, not just that its port is open.
DNS Monitoring
Track DNS resolution and validate that returned records actually match the values you expect — catch a hijacked or silently changed record, not just a resolution failure.
Cron Job Monitoring
Inbound 'I'm alive' checks for cron jobs and background workers — alerts when a run goes missing, with every ping and each run's duration kept.
API Transaction Monitoring
Chain multiple HTTP requests — extract a value from one response, like a login token, and reuse it in the next.
Synthetic Monitoring
Script a real multi-step browser journey — navigate, click, fill, wait, and assert — for user-flow monitoring beyond a simple uptime check.
Most monitoring stacks are actually four tools wearing one logo
Fragmented tooling doesn't just cost money — it costs the minutes between an alert firing and someone understanding what actually broke.
A different tool for every layer
Uptime checks in one tool, server metrics in another, incidents tracked in a third — nothing correlates automatically.
Manual correlation slows every incident
Someone has to stitch together an alert, a metric spike, and a ticket by hand before anyone can even start fixing the actual problem.
RBAC and audit as an afterthought
Coarse, all-or-nothing permissions and no real audit trail make enterprise reviews painful, or impossible to pass.
How it works
External checks and agent metrics land in one platform — with the same alerting, incidents and reporting on top.
- Step 1
Add a check
Pick a monitor type and the regions it runs from. Website, API, DNS, TCP and ping checks run from probes in every region you assign; browser checks run in a real Chromium; cron jobs ping in.
- Step 2
Install the agent (optional)
One installer per host. The agent detects what runs there and installs and supervises the exporters for it — node, containers, PostgreSQL, MySQL, Redis, Nginx, Apache, Kafka, RabbitMQ.
- Step 3
Results are kept
Metrics go to a Prometheus-compatible time-series store; every check result, finding and heartbeat ping is kept in an event store, so history is there when you need it.
- Step 4
See and share
Dashboards from monitor and infrastructure widgets, uptime and SLA reports as PDF, XLSX, CSV or JSON, and public status pages.
How problems are detected
Alerts you can trust — fewer false positives, no duplicate pages, clear routing.
No single-probe false alarms
A monitor checked from several regions is only down when every assigned region agrees — one flaky probe doesn't wake anyone up.
Rules attached automatically
Every monitor type comes with ready-made alert rules that are attached the moment you create a monitor — no rule writing to get started.
Grouped and deduplicated
Alerts are grouped and deduplicated before anyone is notified, and a recovery notice follows when the problem clears.
Routed by severity
Each notification channel can be limited to a severity or an alert category, so the right people get the right alerts.
Maintenance windows
Silence alerts for planned work on the monitors it affects — and only for as long as it lasts.
Thresholds that fit
Consecutive failures, durations and per-type thresholds (response time, Core Web Vitals, Lighthouse scores and more) decide when a check counts as failing.
How problems are managed
From the first alert to the closed incident and the report afterwards.
Incidents from alerts
Incident policies decide which alerts open an incident — so a page goes out for real problems, not for every alert.
A real lifecycle
Open, acknowledged, investigating, identified, monitoring, resolved, closed — or cancelled. Every step is recorded on the incident's timeline.
Automatic priority
P1 to P5, scored from the triggering severity and how many monitors are affected — the same rule every time.
Status pages
Share a public status page for a monitor so customers can see what's happening without asking.
Reports and SLA
Uptime and SLA reports on demand or on a schedule, delivered as PDF, XLSX, CSV or JSON.
Get alerted where your team already works
Eight notification channels out of the box — set one up in a minute and send a test from the app before you rely on it.
- 1
An alert fires
A rule matches — every assigned region agrees the check failed.
- 2
It's routed
Each channel can be limited to a severity or an alert category.
- 3
Your team is told
Every matching channel gets it at once — and again when it recovers.
Any address — one per channel
Slack
Incoming webhook to any channel
Microsoft Teams
Incoming webhook connector
Telegram
Your bot, any chat or group
Discord
Channel webhook
PagerDuty
Events API v2 with your routing key
Opsgenie
Alerts API, priority from severity
Webhook
JSON POST to any URL you own
For developers
Signed event webhooks
Send monitor, alert and incident events to your own systems — every delivery signed (X-MonSPHERE-Signature) and retried on failure.
REST API and API keys
Everything in the app is available over the REST API, with organization API keys you can rotate.
Go and TypeScript SDKs
Official SDKs for the API, so automation is a few lines instead of hand-written HTTP calls.
Teams and workspaces
Organizations, workspaces and roles map MonSPHERE onto how your teams are already split.
Governance built in, not bolted on
Roles, MFA and an audit trail that stand up to a security review — and a deployment that fits where your data has to live.
Custom RBAC
Six system roles plus organization-composable custom roles from a real 12-key permission catalog.
MFA / TOTP
RFC 6238 time-based one-time passcodes with single-use backup codes.
Append-only audit logs
Database-enforced immutable audit trail — not just an application convention.
Platform Admin & feature flags
Cross-organization administration with deterministic, percentage-based feature rollout.
Run it where your data has to live
MonSPHERE Cloud
Fully managed — we run the Postgres, Redis, NATS, and metrics stack. You just install agents.
Self-Hosted
Run the entire stack inside your own infrastructure with the same Docker Compose file we use.
Enterprise
Self-hosted plus an Enterprise license, Platform Admin console, and custom subscription limits.
Simple pricing that scales with you
Start free, upgrade when you need more. Prices come straight from our plan catalog.
Free
For personal projects and small teams getting started with real monitoring.
- Free for 30 days
- 60 api calls / minute
- 2 api keys
- 1 agents
- 50 crawled pages per check
- 3 dashboards
- 3 domains
- 7-day metric retention
- 5 monitors
- 1 organizations
- 3 reports
- 100 sitemap urls per check
- 50 subdomains per check
- 3 users
- 2 webhooks
- 1 workspaces
- Agents Menu
- Email Notifications
- Integrations Menu
- Marketplace Menu
- Status Pages Menu
Professional
For growing teams monitoring production infrastructure.
- 300 api calls / minute
- 20 api keys
- 10 agents
- 500 crawled pages per check
- 25 dashboards
- 30 domains
- 30-day metric retention
- 50 monitors
- 1 organizations
- 25 reports
- 1,000 sitemap urls per check
- 500 subdomains per check
- 25 users
- 20 webhooks
- 10 workspaces
- API Transaction Monitoring
- Accessibility (WCAG) Monitoring
- Advanced HTTP Monitoring
- Advanced TCP Monitoring
- Broken Link Monitoring
- Content Change Monitoring
- Cookie Monitoring
- Core Web Vitals Monitoring
- Dashboard (Home) Menu
- Email Notifications
- Lighthouse Monitoring
- Port Discovery Monitoring
- SLA Menu
- Sitemap & URL Monitoring
- Status Pages Menu
- Subdomain Monitoring
- Synthetic Monitoring
- Third-Party Script Integrity Monitoring
- Typosquatting & Brand Impersonation Monitoring
Enterprise
For organizations with custom scale, compliance, and support needs.
- 1,000 api calls / minute
- 100 api keys
- 100 agents
- 5,000 crawled pages per check
- 250 dashboards
- 300 domains
- 365-day metric retention
- 500 monitors
- 1 organizations
- 250 reports
- 10,000 sitemap urls per check
- 5,000 subdomains per check
- 250 users
- 100 webhooks
- 100 workspaces
Custom
For air-gapped, on-prem, or MSP deployments with negotiated terms.
- 1,000 api calls / minute
- 100 api keys
- 100 agents
- 5,000 crawled pages per check
- 250 dashboards
- 300 domains
- 365-day metric retention
- 500 monitors
- 1 organizations
- 250 reports
- 10,000 sitemap urls per check
- 5,000 subdomains per check
- 250 users
- 100 webhooks
- 100 workspaces
Frequently asked questions
Start monitoring everything in minutes
Create a free account, add your first check and get alerted the moment something breaks — no credit card required.